Chung-Ang University
NAVER Cloud
Lunit Inc.


Synthesizing a target concept from a single reference image remains challenging in diffusion-based personalized text-to-image generation, particularly when prompts require explicit attribute edits. In the sticker domain, test-time fine-tuning methods often overfit to the reference image and suffer from visual entanglement and structural rigidity. We introduce SEAL, a plug-and-play, architecture-agnostic adaptation module that combines a Semantic-guided Spatial Attention Loss, a Split-merge Token Strategy, and a Structure-aware Layer Restriction. We also introduce StickerBench, a large-scale sticker dataset with six structured attributes for controlled evaluation of identity disentanglement and contextual controllability in single-image sticker personalization.
SEAL is a plug-and-play module for existing personalization pipelines.
Aligns the concept-token cross-attention map with the object region predicted by SAM, suppressing background leakage and improving identity disentanglement.
Optimizes multiple auxiliary embeddings and merges them into one concept embedding, improving optimization stability under single-image supervision.
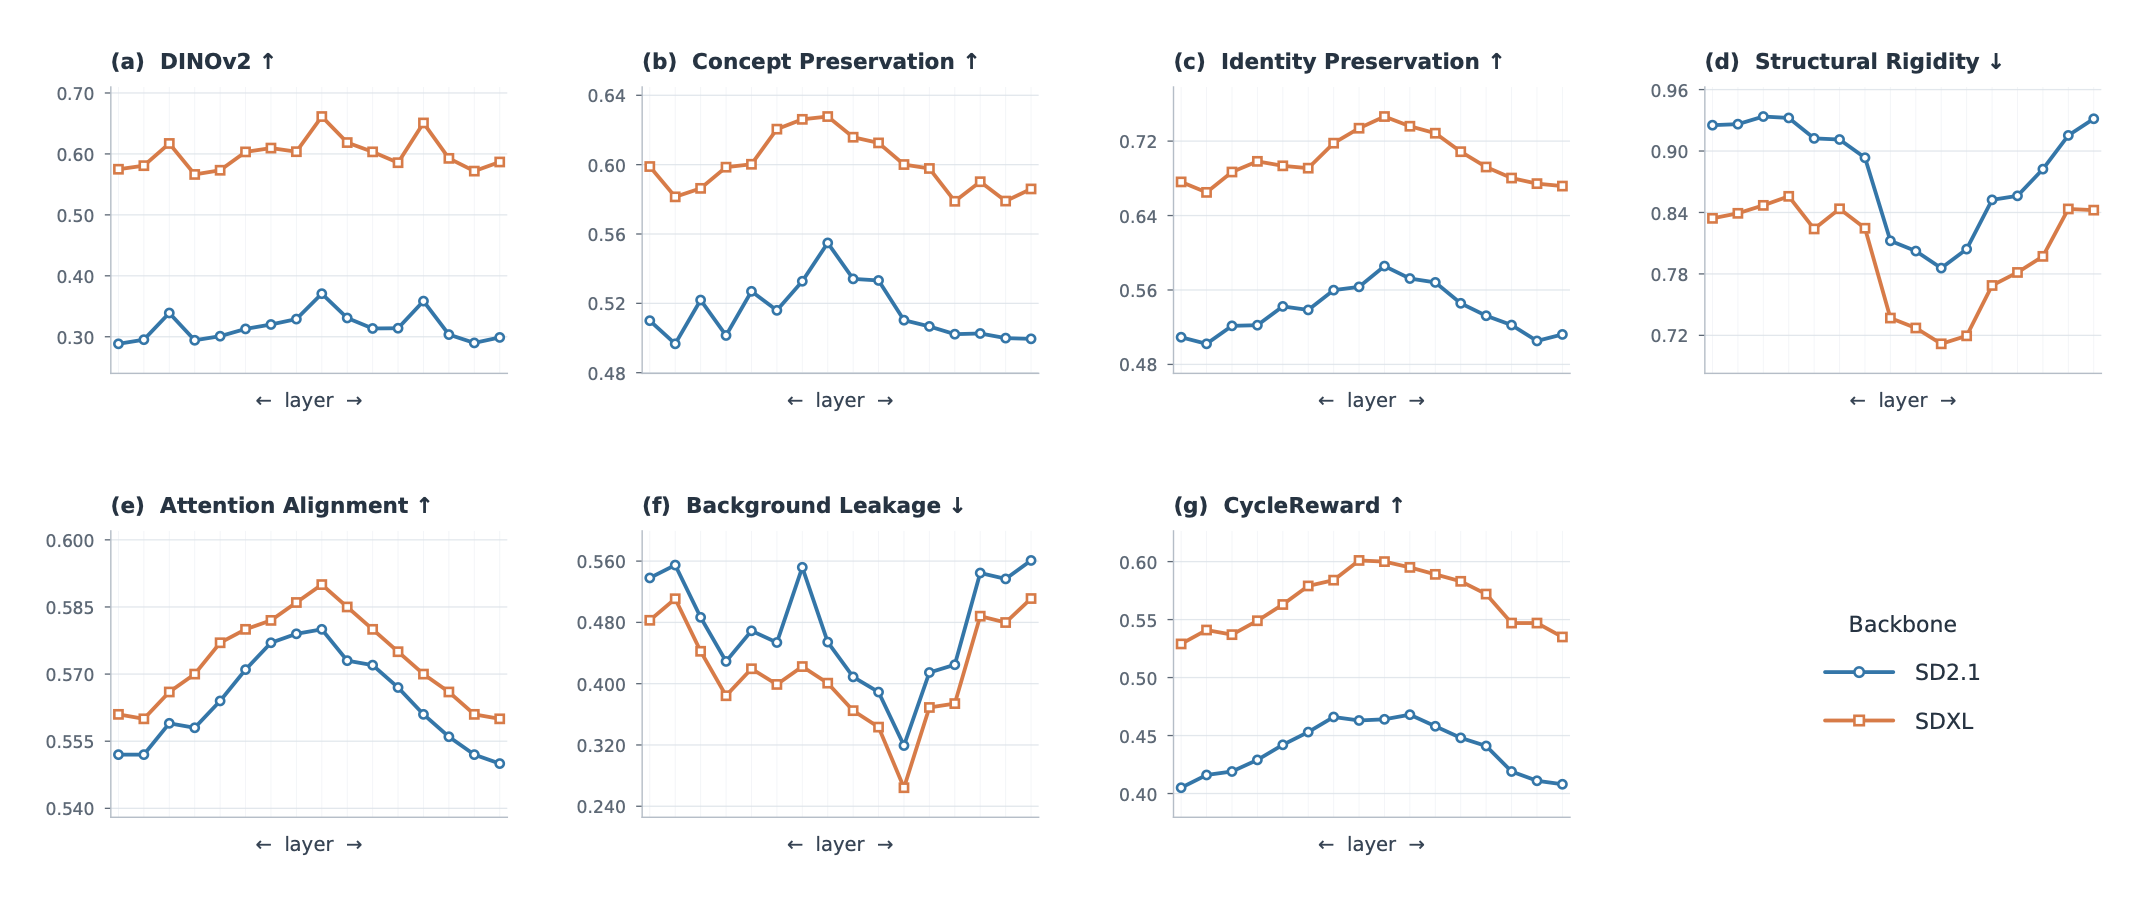
Applies spatial supervision only to semantically informative cross-attention layers, reducing overfitting to low-level layout patterns.
SEAL is designed to reduce the two dominant failure modes in single-image sticker personalization.
Existing methods often memorize the reference-specific layout, which reduces flexibility under action, pose, and composition edits.
Existing methods may absorb background cues into the learned concept representation, causing identity and context to become entangled.
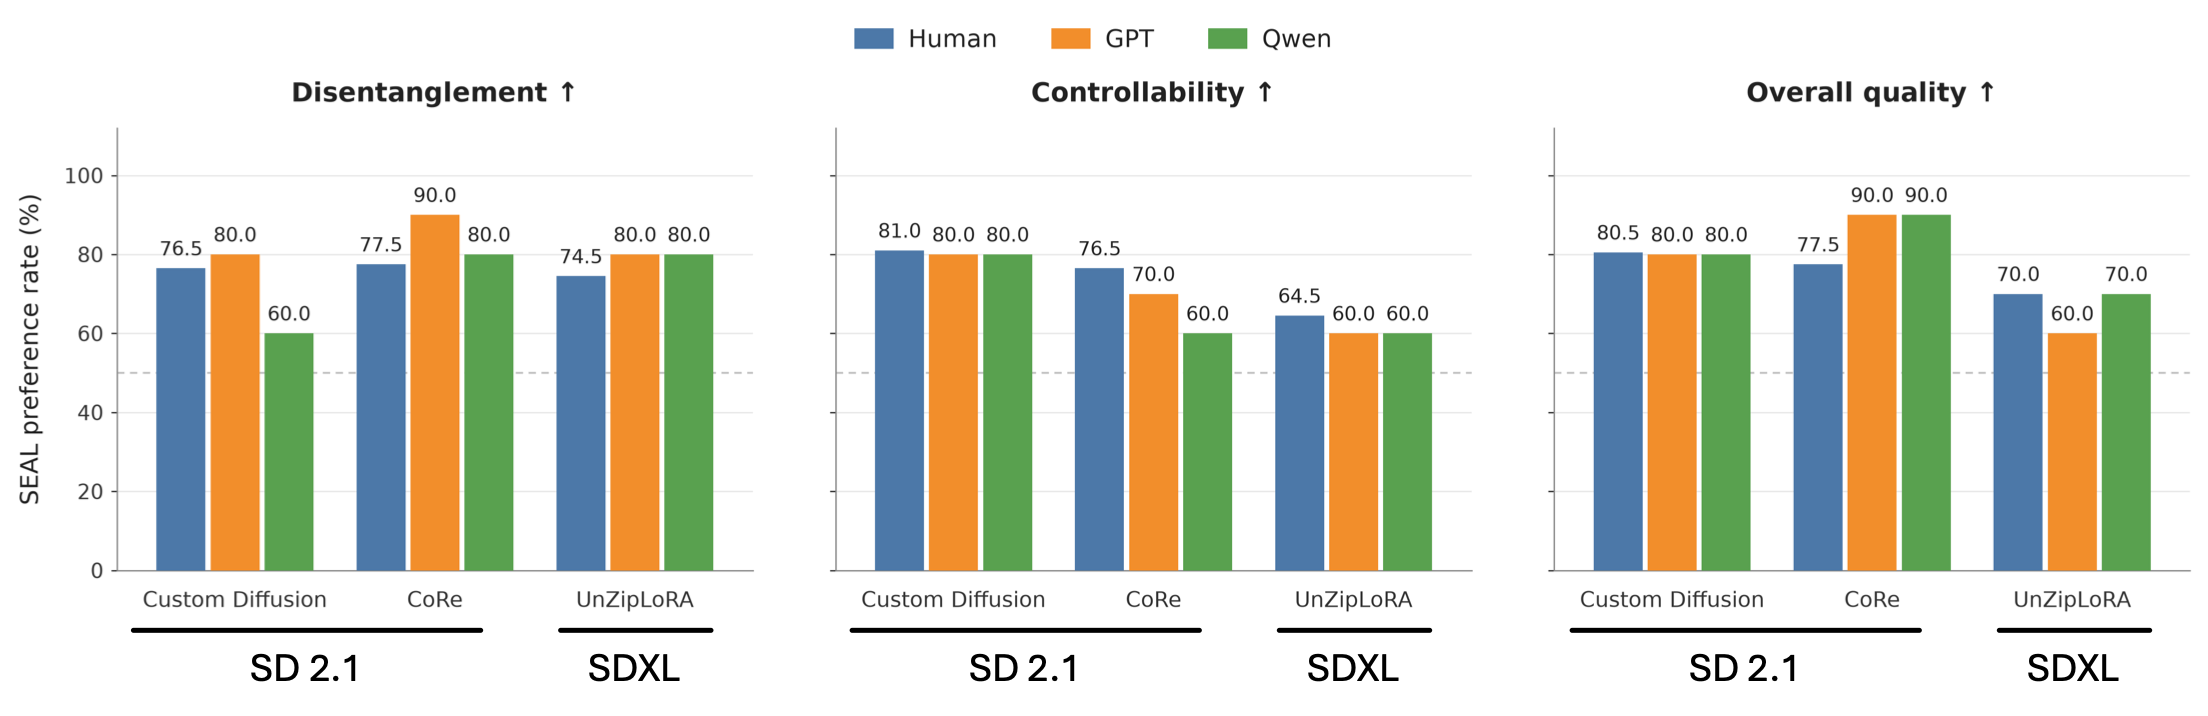
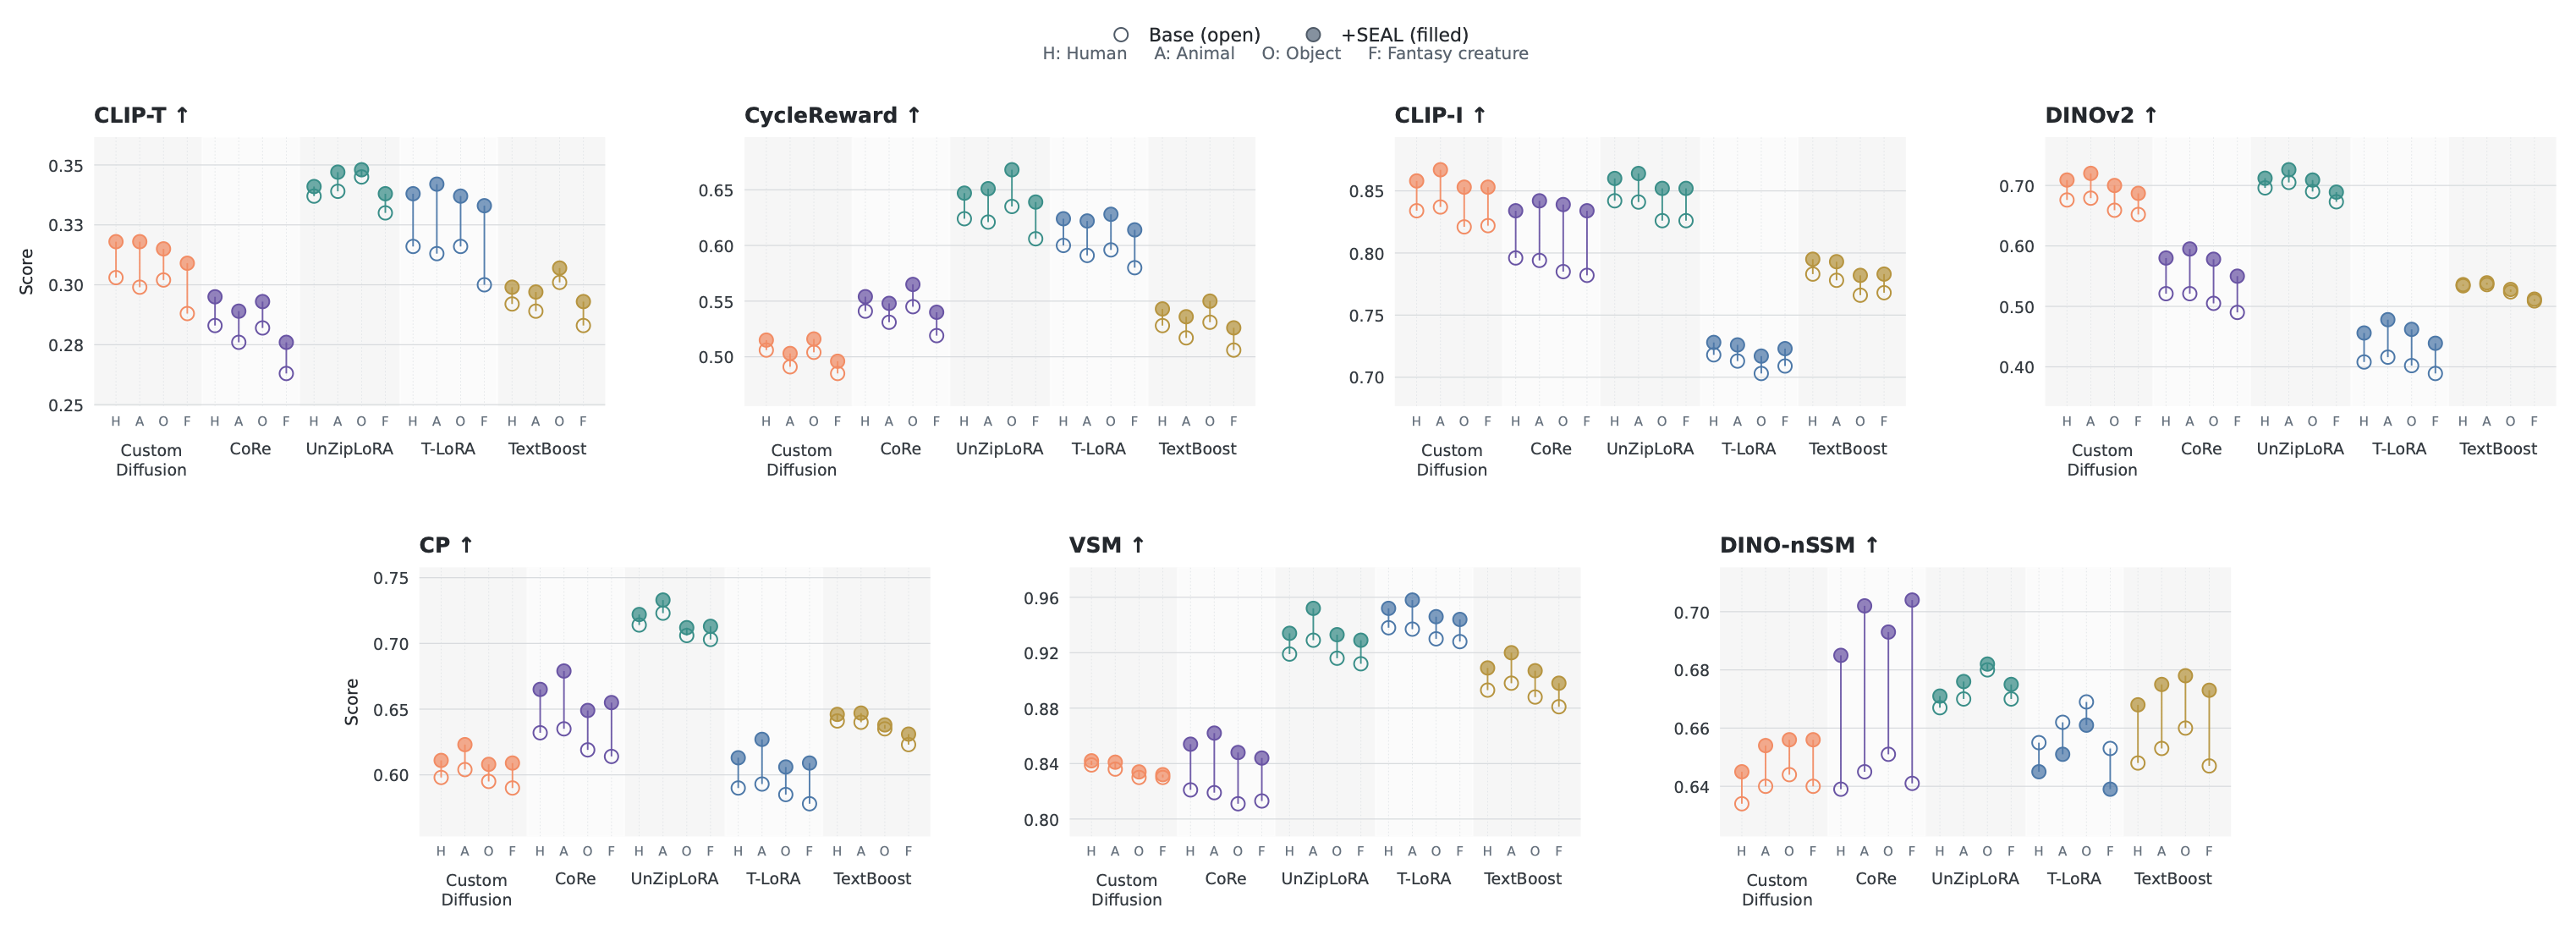
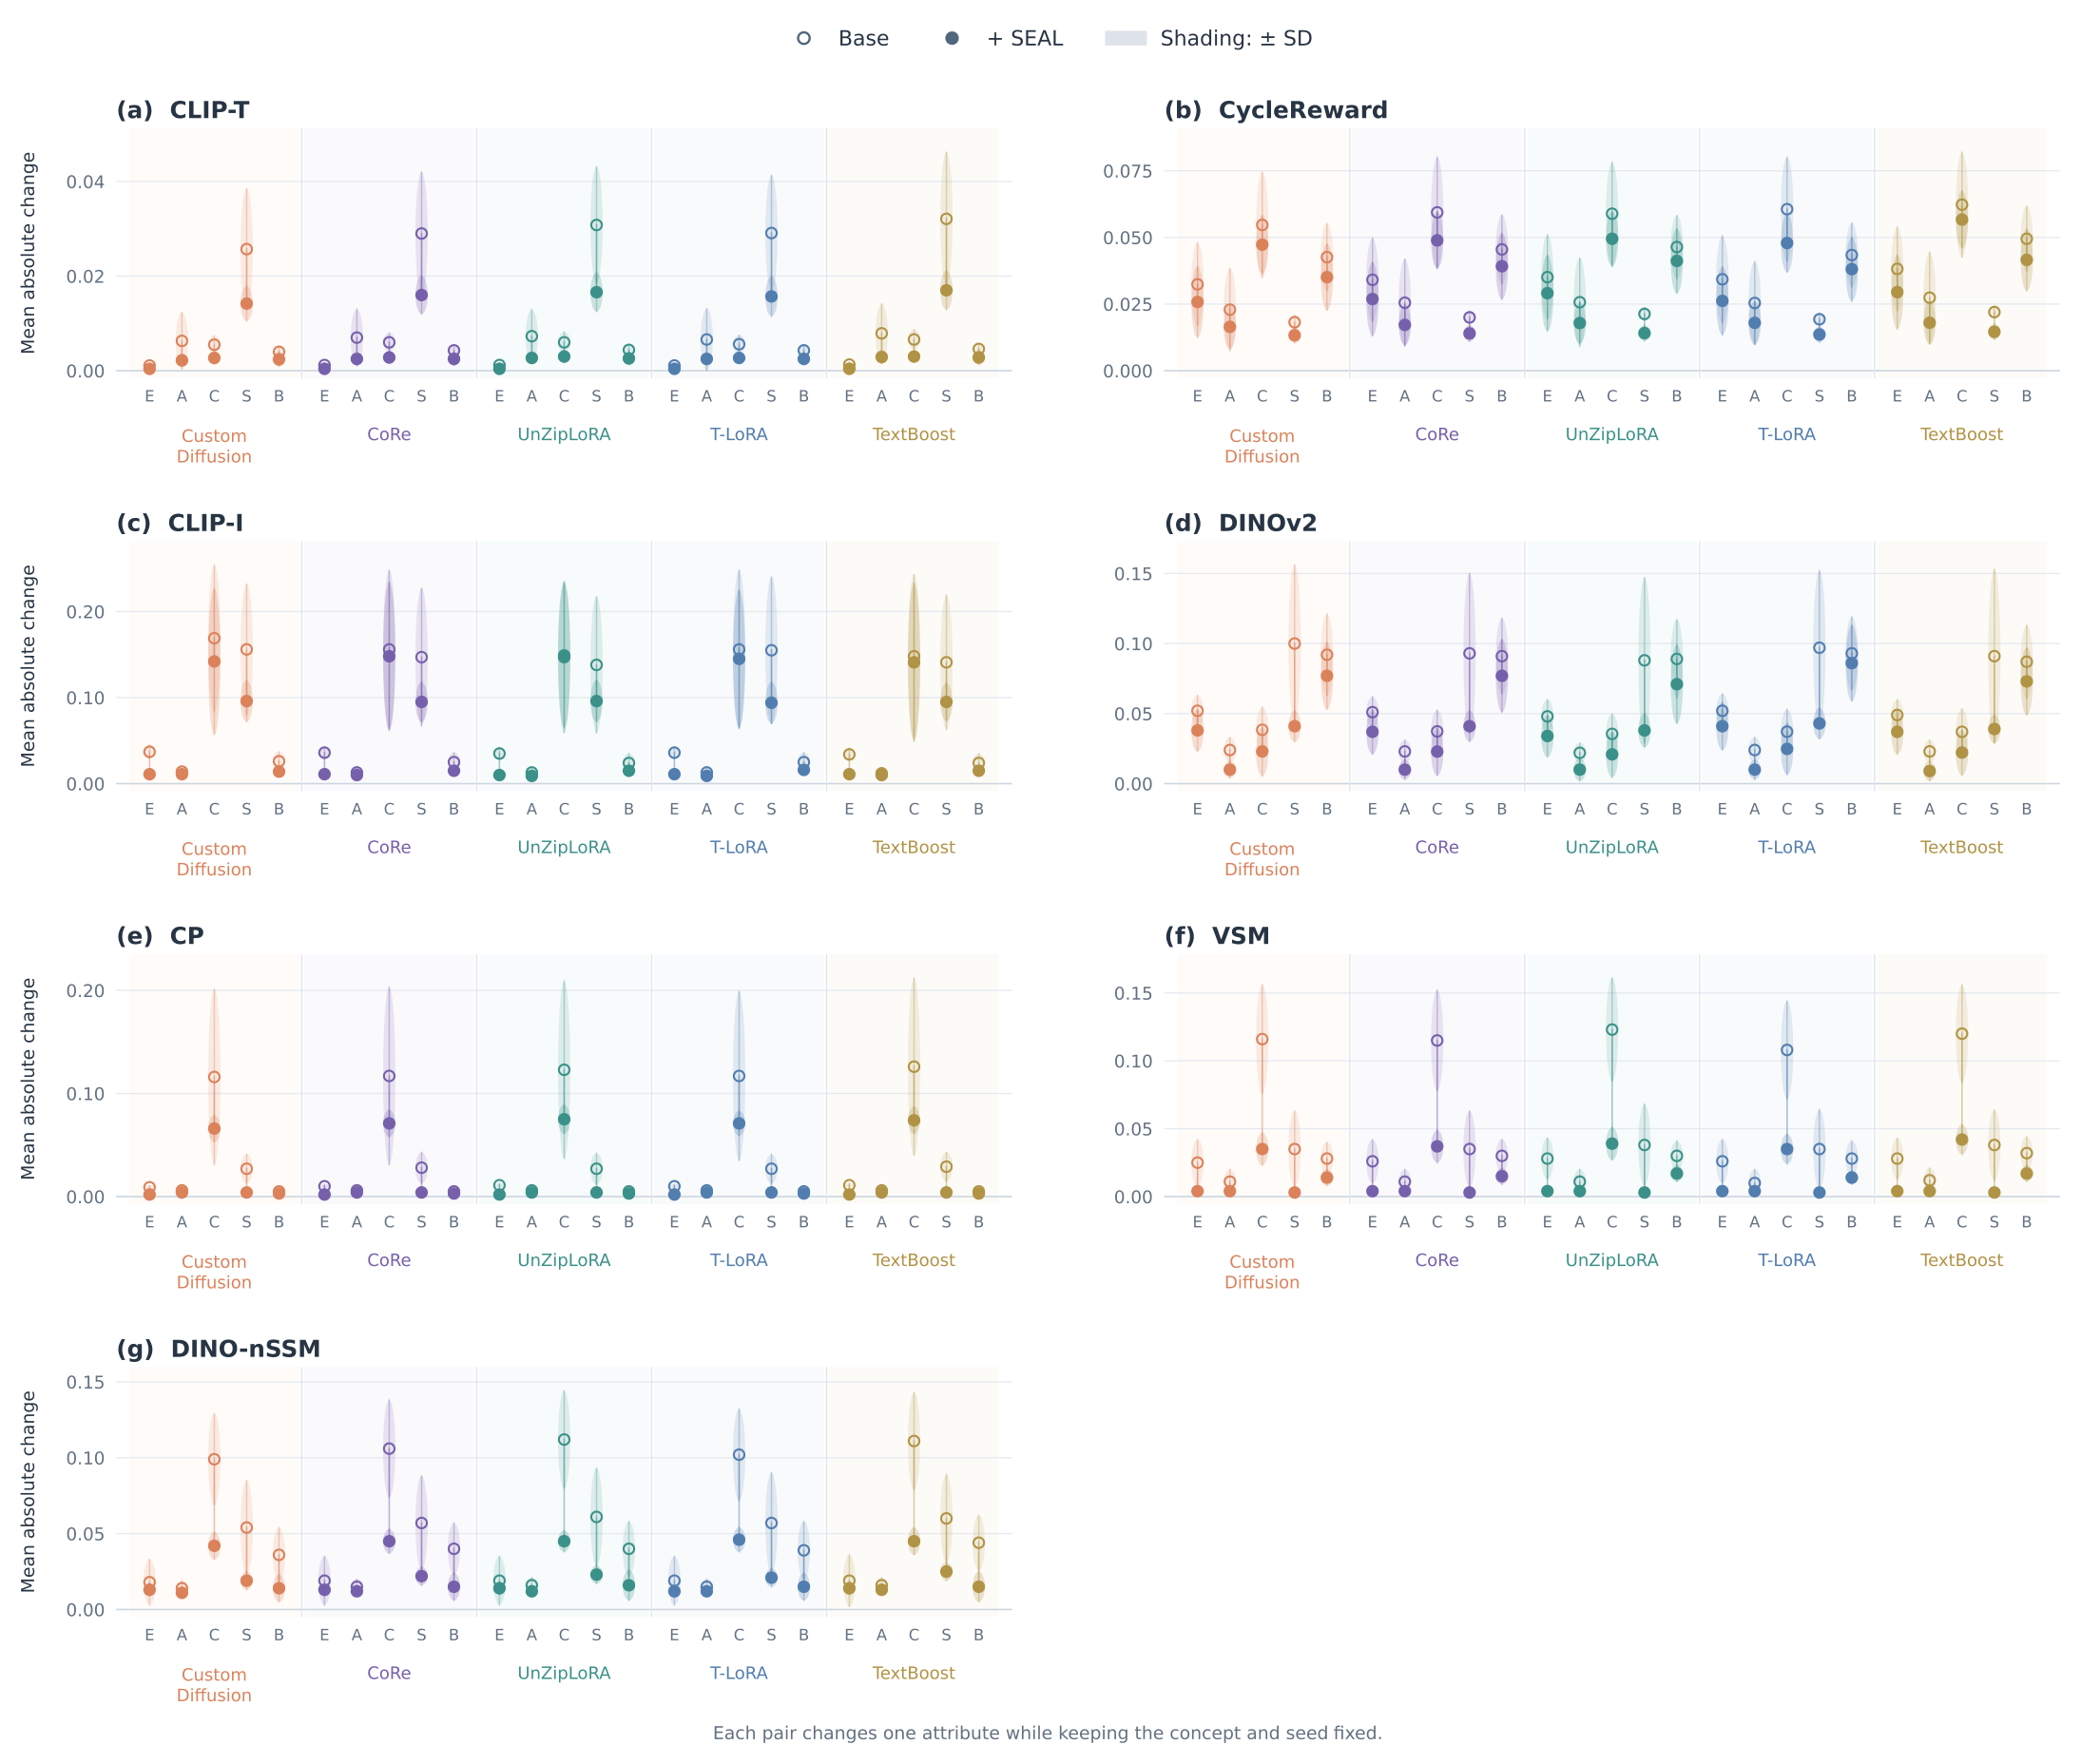
Quantitative comparisons from the revised manuscript, paired with visual analyses of SEAL's adaptation behavior.
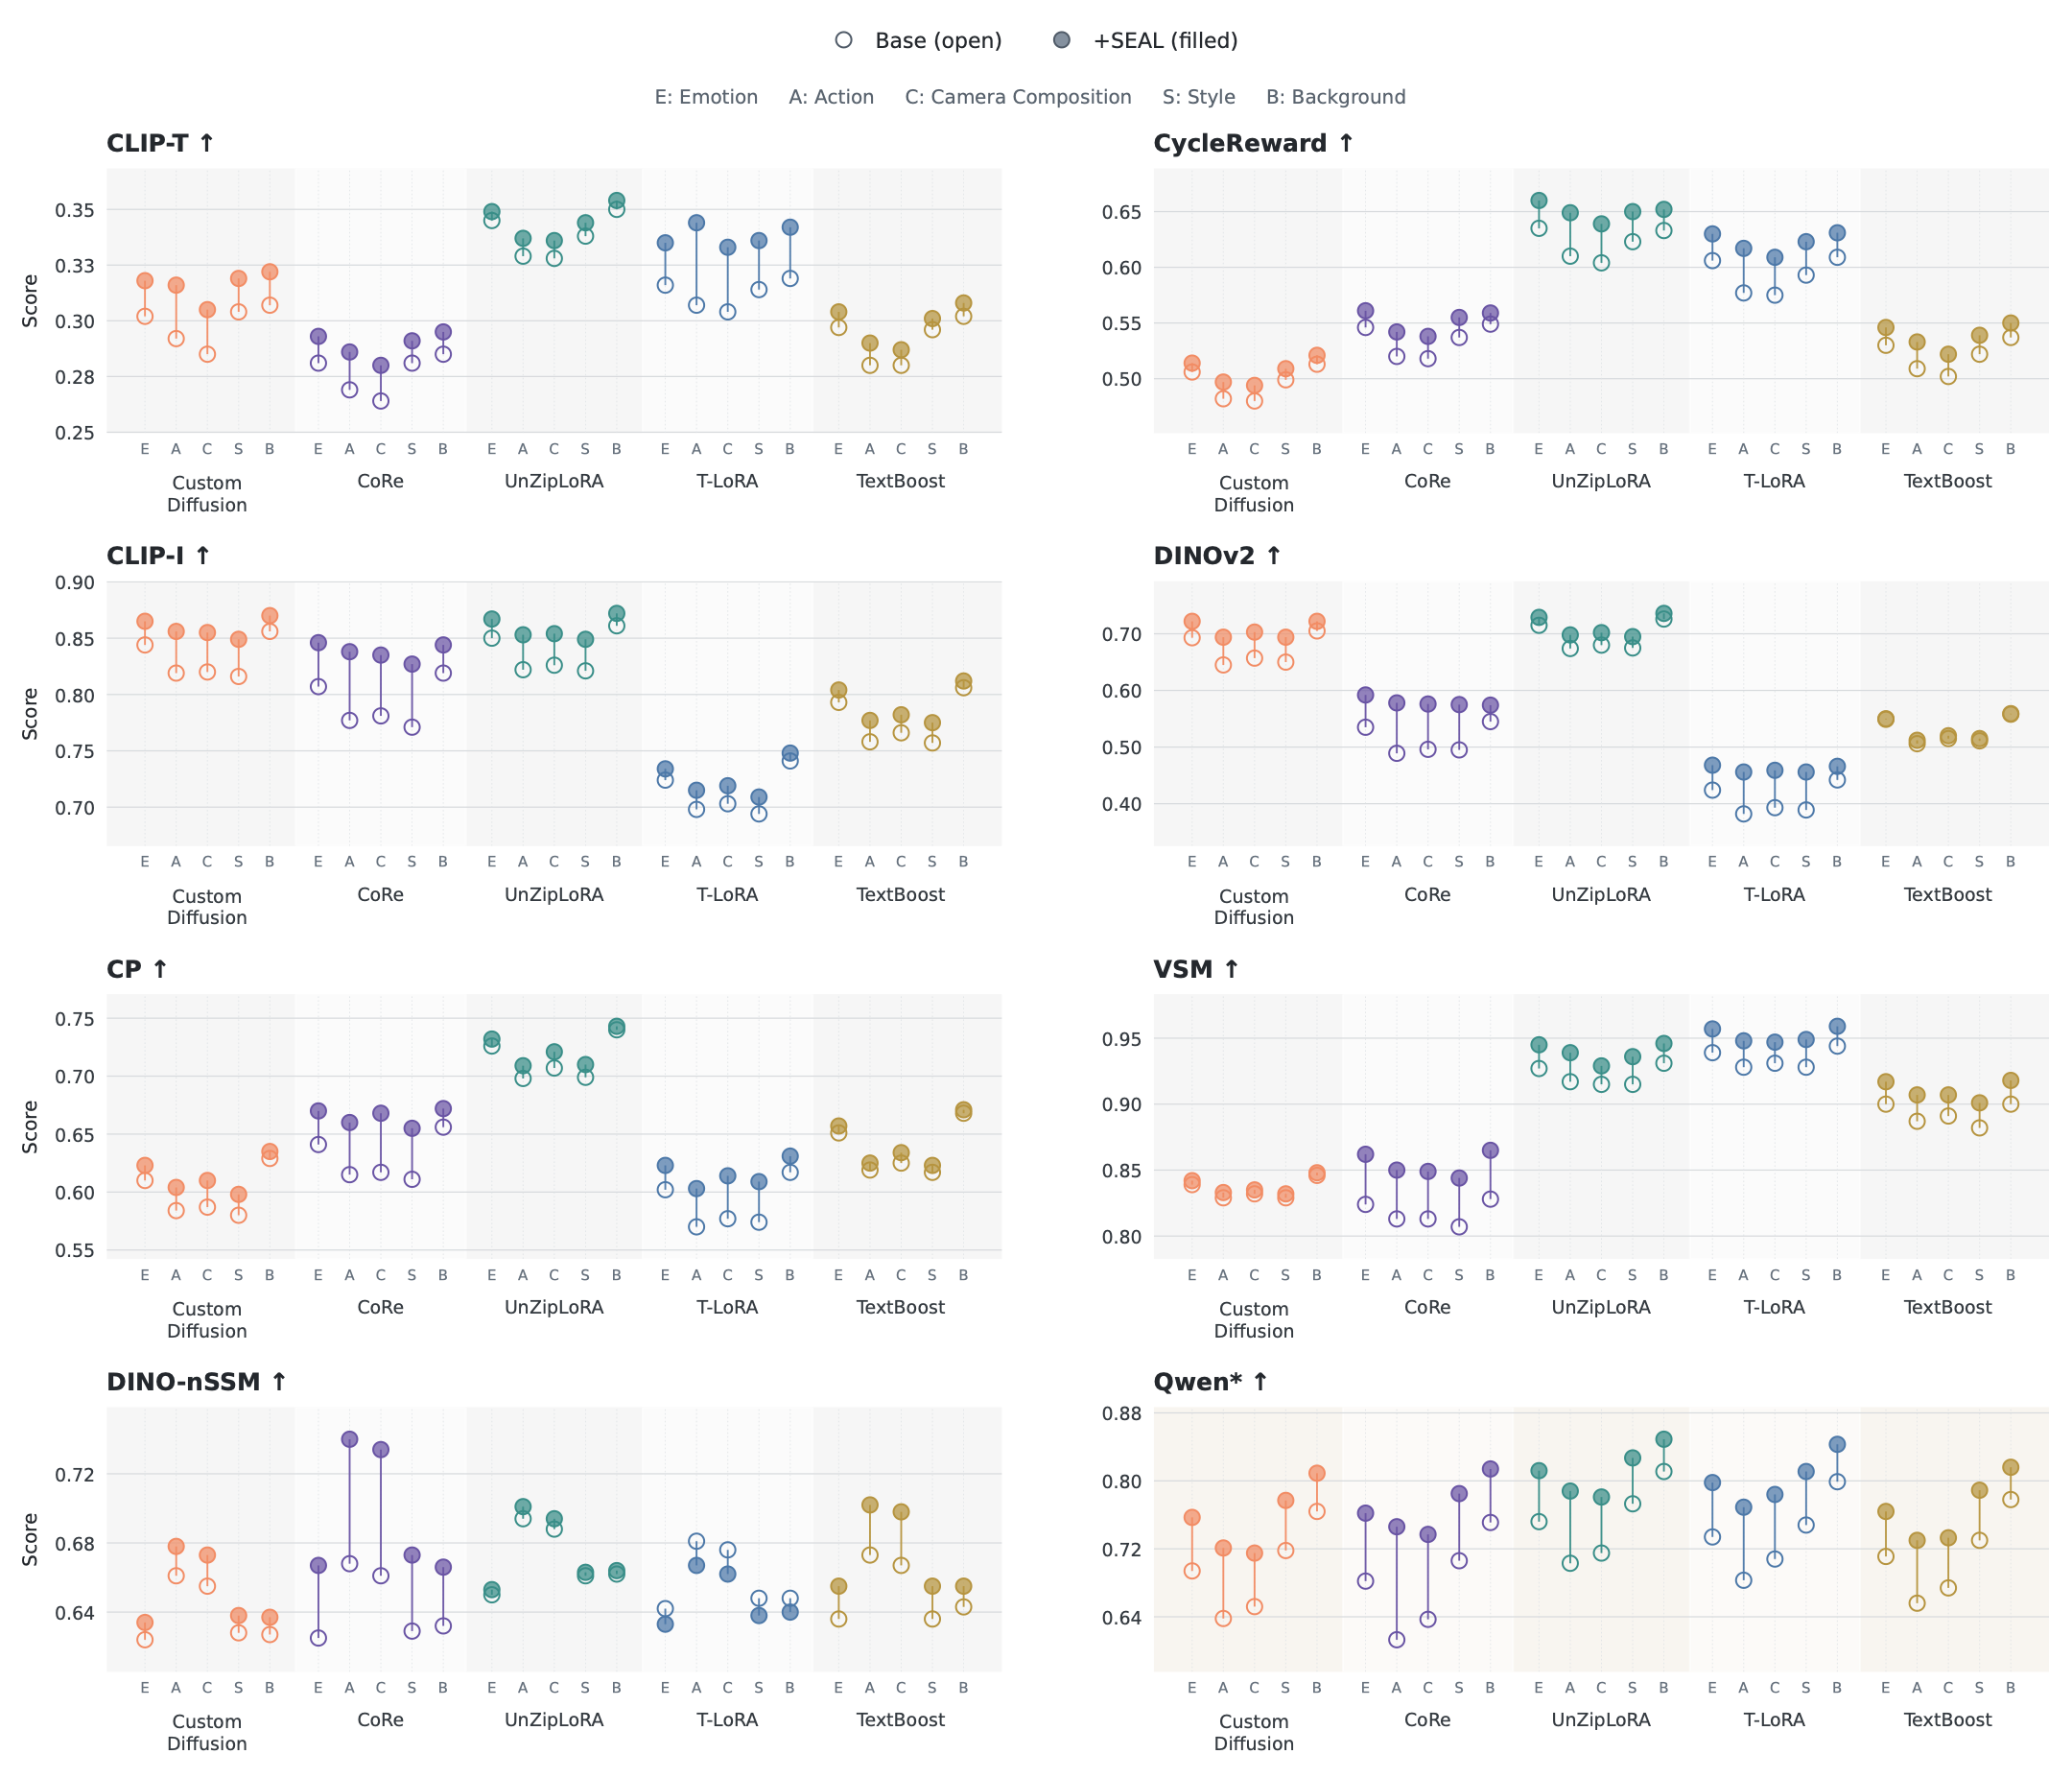
Each cell compares a baseline with its SEAL-integrated variant. Scores are averaged across 20 prompts and 10 inference seeds per concept.
| Method | CLIP-T ↑ | CycleReward ↑ |
|---|---|---|
| Textual Inversion | 0.2710.296(+0.025) 95% CI [0.259, 0.283] → [0.284, 0.308] | 0.4760.487(+0.011) 95% CI [0.465, 0.487] → [0.476, 0.498] |
| DreamBooth | 0.2910.311(+0.020) 95% CI [0.279, 0.303] → [0.300, 0.322] | 0.4730.498(+0.025) 95% CI [0.460, 0.486] → [0.485, 0.511] |
| AttnDreamBooth | 0.2570.286(+0.029) 95% CI [0.247, 0.267] → [0.277, 0.295] | 0.4880.476(-0.012) 95% CI [0.477, 0.499] → [0.465, 0.487] |
| ClassDiffusion | 0.2910.288(-0.003) 95% CI [0.288, 0.294] → [0.285, 0.291] | 0.4820.499(+0.017) 95% CI [0.471, 0.493] → [0.486, 0.512] |
| Custom Diffusion | 0.2980.316(+0.018) 95% CI [0.288, 0.308] → [0.307, 0.325] | 0.4960.507(+0.011) 95% CI [0.485, 0.507] → [0.496, 0.518] |
| CoRe | 0.2760.289(+0.013) 95% CI [0.267, 0.285] → [0.280, 0.298] | 0.5340.551(+0.017) 95% CI [0.523, 0.545] → [0.539, 0.563] |
| UnZipLoRA | 0.3380.344(+0.006) 95% CI [0.331, 0.345] → [0.336, 0.352] | 0.6210.650(+0.029) 95% CI [0.610, 0.632] → [0.640, 0.660] |
| T-LoRA | 0.3120.338(+0.026) 95% CI [0.302, 0.322] → [0.329, 0.347] | 0.5920.622(+0.030) 95% CI [0.580, 0.604] → [0.611, 0.633] |
| TextBoost | 0.2910.298(+0.007) 95% CI [0.284, 0.298] → [0.290, 0.306] | 0.5200.538(+0.018) 95% CI [0.508, 0.532] → [0.526, 0.550] |
| Method | CLIP-I ↑ | DINOv2 ↑ | CP ↑ | VSM ↑ |
|---|---|---|---|---|
| Textual Inversion | 0.6850.671(-0.014) 95% CI [0.670, 0.700] → [0.657, 0.685] | 0.4030.437(+0.034) 95% CI [0.369, 0.437] → [0.403, 0.471] | 0.5650.569(+0.004) 95% CI [0.561, 0.569] → [0.565, 0.573] | 0.7980.800(+0.002) 95% CI [0.796, 0.800] → [0.798, 0.802] |
| DreamBooth | 0.5900.628(+0.038) 95% CI [0.566, 0.614] → [0.604, 0.652] | 0.3040.421(+0.117) 95% CI [0.267, 0.341] → [0.383, 0.459] | 0.5790.594(+0.015) 95% CI [0.564, 0.594] → [0.580, 0.608] | 0.8060.798(-0.008) 95% CI [0.798, 0.814] → [0.790, 0.806] |
| AttnDreamBooth | 0.7710.783(+0.012) 95% CI [0.758, 0.784] → [0.771, 0.795] | 0.5330.597(+0.064) 95% CI [0.500, 0.566] → [0.569, 0.625] | 0.5680.587(+0.019) 95% CI [0.555, 0.581] → [0.574, 0.600] | 0.8200.822(+0.002) 95% CI [0.818, 0.822] → [0.820, 0.824] |
| ClassDiffusion | 0.7510.790(+0.039) 95% CI [0.729, 0.773] → [0.769, 0.811] | 0.6560.691(+0.035) 95% CI [0.621, 0.691] → [0.656, 0.726] | 0.6020.638(+0.036) 95% CI [0.586, 0.618] → [0.622, 0.654] | 0.8280.852(+0.024) 95% CI [0.819, 0.837] → [0.842, 0.862] |
| Custom Diffusion | 0.8310.859(+0.028) 95% CI [0.814, 0.848] → [0.840, 0.878] | 0.6700.707(+0.037) 95% CI [0.641, 0.699] → [0.678, 0.736] | 0.5980.614(+0.016) 95% CI [0.586, 0.610] → [0.601, 0.627] | 0.8350.838(+0.003) 95% CI [0.831, 0.839] → [0.835, 0.841] |
| CoRe | 0.7910.838(+0.047) 95% CI [0.774, 0.808] → [0.821, 0.855] | 0.5120.579(+0.067) 95% CI [0.482, 0.542] → [0.551, 0.607] | 0.6280.665(+0.037) 95% CI [0.616, 0.640] → [0.652, 0.678] | 0.8170.854(+0.037) 95% CI [0.816, 0.818] → [0.831, 0.877] |
| UnZipLoRA | 0.8360.859(+0.023) 95% CI [0.818, 0.854] → [0.841, 0.877] | 0.6940.712(+0.018) 95% CI [0.672, 0.716] → [0.691, 0.733] | 0.7140.723(+0.009) 95% CI [0.703, 0.725] → [0.711, 0.735] | 0.9210.939(+0.018) 95% CI [0.912, 0.930] → [0.931, 0.947] |
| T-LoRA | 0.7120.725(+0.013) 95% CI [0.698, 0.726] → [0.712, 0.738] | 0.4060.461(+0.055) 95% CI [0.372, 0.440] → [0.426, 0.496] | 0.5880.616(+0.028) 95% CI [0.573, 0.603] → [0.602, 0.630] | 0.9340.952(+0.018) 95% CI [0.925, 0.943] → [0.943, 0.961] |
| TextBoost | 0.7760.790(+0.014) 95% CI [0.761, 0.791] → [0.774, 0.806] | 0.5280.531(+0.003) 95% CI [0.524, 0.532] → [0.527, 0.535] | 0.6360.642(+0.006) 95% CI [0.630, 0.642] → [0.636, 0.648] | 0.8920.910(+0.018) 95% CI [0.889, 0.895] → [0.894, 0.926] |
| Method | DINO-nSSM ↑ |
|---|---|
| Textual Inversion | 0.6130.633(+0.020) 95% CI [0.594, 0.632] → [0.615, 0.651] |
| DreamBooth | 0.6270.661(+0.034) 95% CI [0.604, 0.650] → [0.639, 0.683] |
| AttnDreamBooth | 0.6300.644(+0.014) 95% CI [0.616, 0.644] → [0.630, 0.658] |
| ClassDiffusion | 0.6240.641(+0.017) 95% CI [0.605, 0.643] → [0.624, 0.658] |
| Custom Diffusion | 0.6390.652(+0.013) 95% CI [0.624, 0.654] → [0.637, 0.667] |
| CoRe | 0.6430.696(+0.053) 95% CI [0.624, 0.662] → [0.679, 0.713] |
| UnZipLoRA | 0.6710.675(+0.004) 95% CI [0.666, 0.676] → [0.671, 0.679] |
| T-LoRA | 0.6590.648(-0.011) 95% CI [0.645, 0.673] → [0.635, 0.661] |
| TextBoost | 0.6510.673(+0.022) 95% CI [0.633, 0.669] → [0.652, 0.694] |
Mean scores and 95% concept-level bootstrap confidence intervals are from the revised main comparison. DINO-nSSM is interpreted together with identity preservation and prompt alignment.
CoRe and CoRe + SEAL use matched reference images, prompts, and inference settings.
| Edited attribute · Method | Attention leakage ↓ | Background similarity | CLIP-T ↑ | CycleReward ↑ |
|---|---|---|---|---|
| Background · CoRe | 0.512 | 0.135 | 0.285 | 0.549 |
| Background · +SEAL | 0.489 | 0.026 | 0.295 | 0.559 |
| Action · CoRe | 0.503 | 0.119 | 0.269 | 0.520 |
| Action · +SEAL | 0.487 | 0.062 | 0.286 | 0.542 |
| Camera Composition · CoRe | 0.482 | 0.353 | 0.264 | 0.518 |
| Camera Composition · +SEAL | 0.453 | 0.178 | 0.280 | 0.538 |
| Emotion · CoRe | 0.424 | 0.092 | 0.281 | 0.546 |
| Emotion · +SEAL | 0.420 | 0.053 | 0.293 | 0.561 |
| Style · CoRe | 0.588 | 0.278 | 0.281 | 0.537 |
| Style · +SEAL | 0.550 | 0.214 | 0.291 | 0.555 |
Background similarity is lower-is-better only for the Background-edit condition. For other edits it has no preferred direction.
Five baselines and their SEAL variants are evaluated with the same reference, prompts, and inference settings within each pair.
| Method | CLIP-T ↑ | CycleReward ↑ | DINO-nSSM ↑ |
|---|---|---|---|
| Custom Diffusion | 0.2810.285(+0.004) | 0.5090.530(+0.021) | 0.6430.673(+0.030) |
| CoRe | 0.2740.291(+0.017) | 0.5460.535(-0.011) | 0.6300.660(+0.030) |
| UnZipLoRA | 0.3170.324(+0.007) | 0.6170.604(-0.013) | 0.6780.706(+0.028) |
| T-LoRA | 0.3090.326(+0.017) | 0.5980.617(+0.019) | 0.6590.662(+0.003) |
| TextBoost | 0.3040.297(-0.007) | 0.5150.536(+0.021) | 0.6640.691(+0.027) |
| Method | CLIP-I ↑ | DINOv2 ↑ | CP ↑ | VSM ↑ |
|---|---|---|---|---|
| Custom Diffusion | 0.7480.797(+0.049) | 0.5350.557(+0.022) | 0.5970.599(+0.002) | 0.8410.852(+0.011) |
| CoRe | 0.7540.773(+0.019) | 0.5080.562(+0.054) | 0.6190.626(+0.007) | 0.8300.849(+0.019) |
| UnZipLoRA | 0.8030.864(+0.061) | 0.6390.708(+0.069) | 0.7040.725(+0.021) | 0.9060.897(-0.009) |
| T-LoRA | 0.7870.802(+0.015) | 0.4510.476(+0.025) | 0.5950.626(+0.031) | 0.9290.937(+0.008) |
| TextBoost | 0.7910.815(+0.024) | 0.5390.564(+0.025) | 0.6310.663(+0.032) | 0.9000.909(+0.009) |
Values are from the revised cross-dataset comparison. Changes across individual metrics can trade off; DINO-nSSM is read alongside identity and prompt scores.
All eight combinations of Spatial Attention Loss (SL), Split-merge Token Strategy (ST), and Layer Restriction (LR).
| Components | CLIP-T ↑ | CycleReward ↑ | CLIP-I ↑ | DINOv2 ↑ | CP ↑ | DINO-nSSM ↑ |
|---|---|---|---|---|---|---|
| None | 0.276 | 0.534 | 0.791 | 0.512 | 0.628 | 0.643 |
| SL | 0.263 | 0.456 | 0.884 | 0.481 | 0.530 | 0.647 |
| ST | 0.296 | 0.439 | 0.821 | 0.461 | 0.600 | 0.651 |
| LR | 0.269 | 0.484 | 0.904 | 0.575 | 0.578 | 0.673 |
| SL + ST | 0.264 | 0.497 | 0.879 | 0.419 | 0.639 | 0.654 |
| SL + LR | 0.283 | 0.536 | 0.808 | 0.480 | 0.612 | 0.685 |
| ST + LR | 0.280 | 0.523 | 0.791 | 0.463 | 0.650 | 0.688 |
| Full SEAL | 0.289 | 0.551 | 0.838 | 0.579 | 0.665 | 0.696 |
The full configuration has the highest CycleReward, DINOv2, CP, and DINO-nSSM among these eight settings.
The selected K = 5 balances the three reported metrics.
| Setting | CLIP-T ↑ | CLIP-I ↑ | DINOv2 ↑ |
|---|---|---|---|
| K = 1 | 0.313 | 0.819 | 0.480 |
| K = 3 | 0.308 | 0.833 | 0.483 |
| K = 5 (selected) | 0.306 | 0.849 | 0.591 |
| K = 7 | 0.290 | 0.884 | 0.479 |
Structured tags are most effective when used consistently.
| Adaptation → inference | CLIP-T ↑ | CLIP-I ↑ | DINOv2 ↑ |
|---|---|---|---|
| Sentence → Sentence | 0.261 | 0.854 | 0.423 |
| Sentence → Tag | 0.258 | 0.813 | 0.389 |
| Tag → Sentence | 0.273 | 0.529 | 0.369 |
| Tag → Tag | 0.306 | 0.849 | 0.591 |
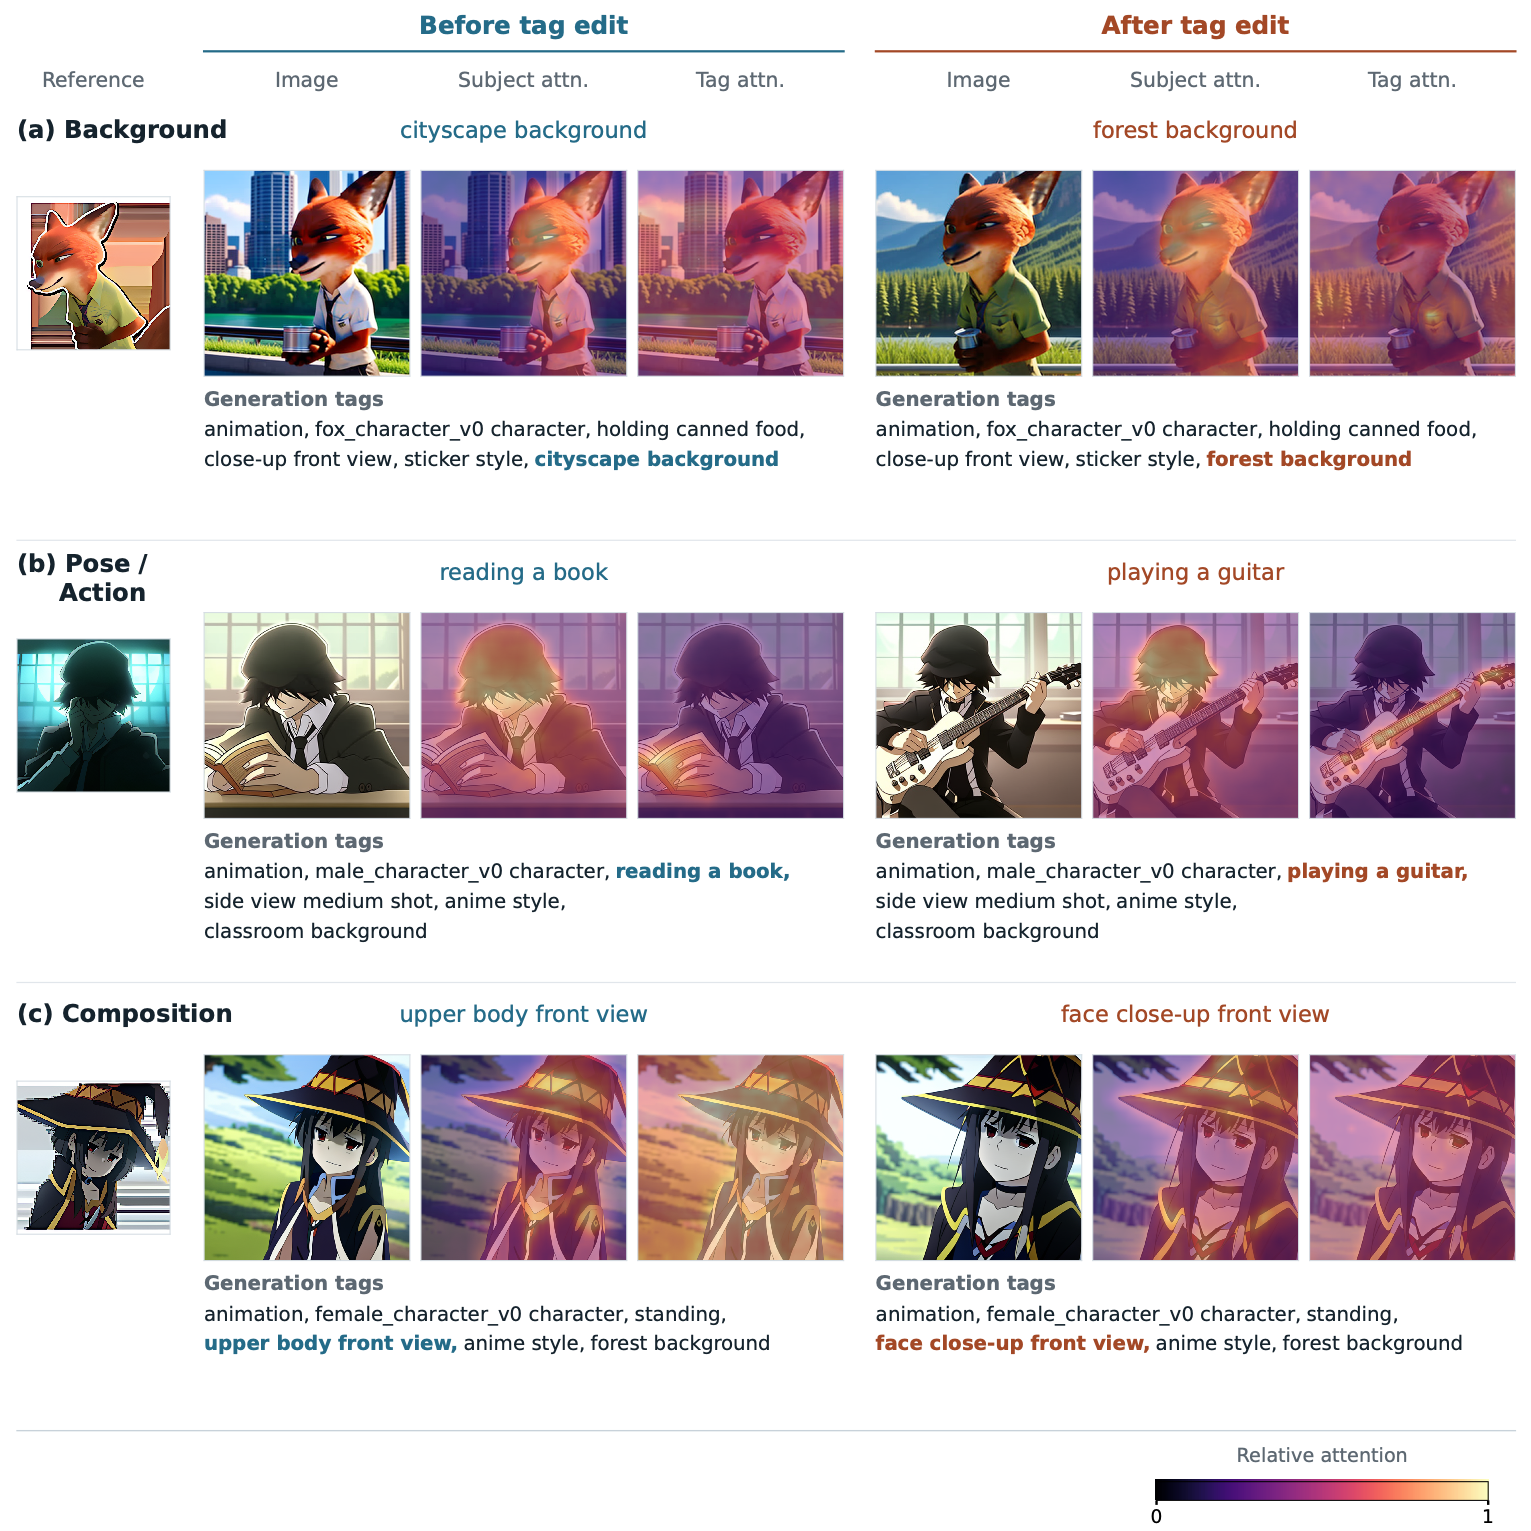
Qualitative ablations and attention maps from the manuscript.


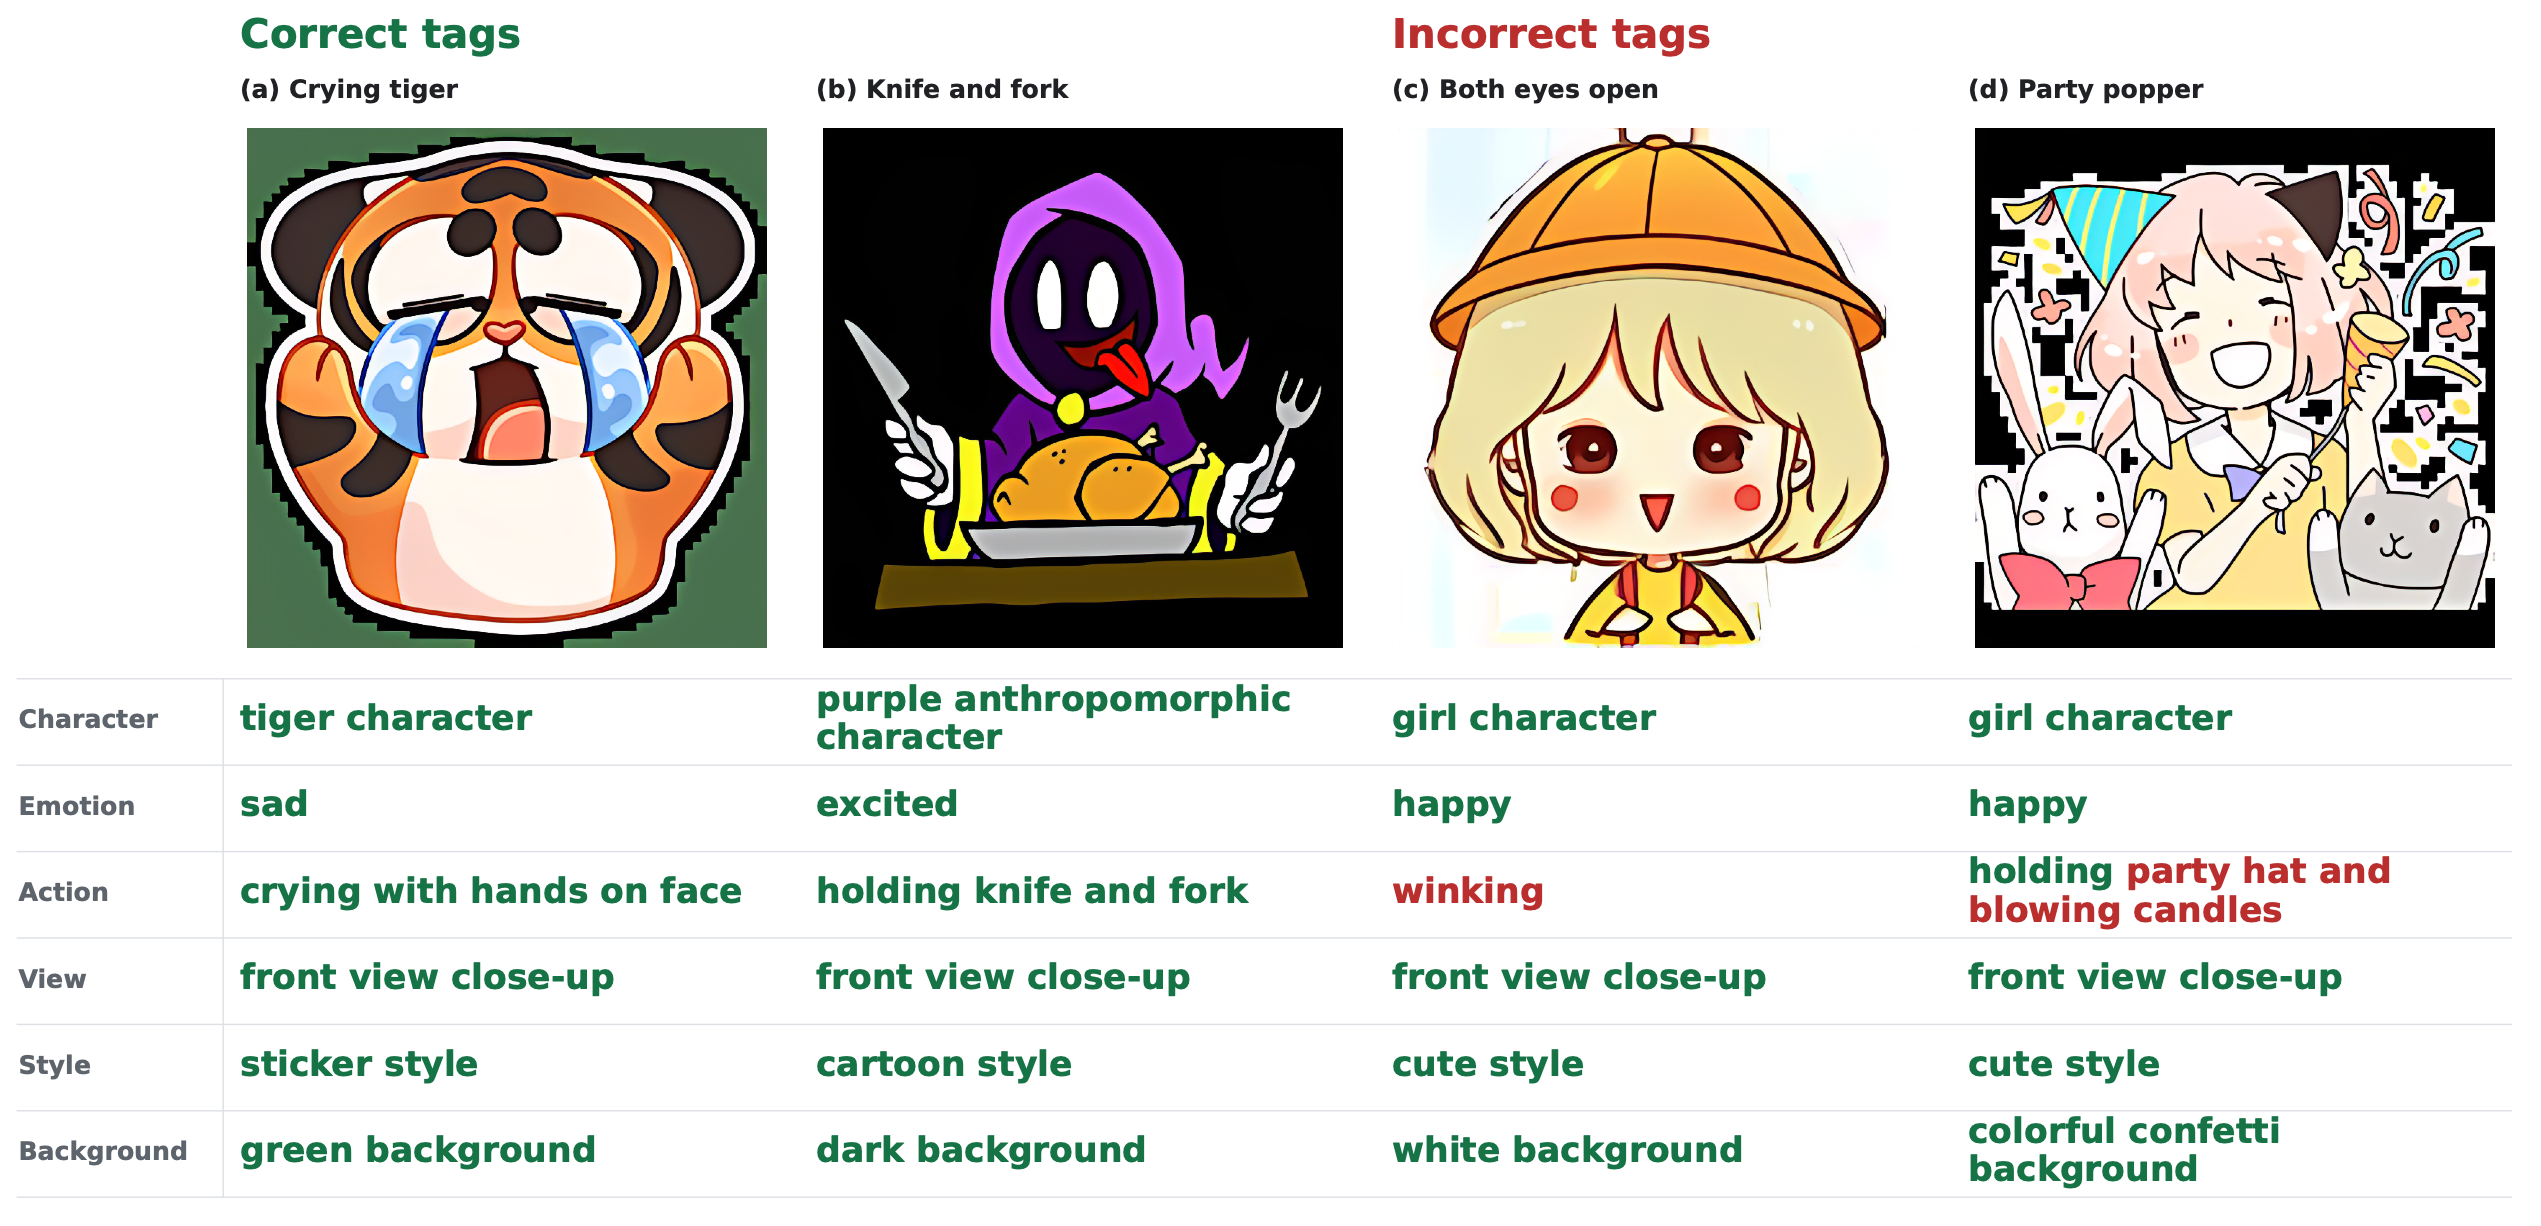
A curated sticker dataset with structured tags for controlled, single-image personalization evaluation.
Appearance anchors the concept; the remaining fields support controlled prompt edits.
@misc{roh2026sealsemanticawaresingleimagesticker,
title={SEAL: Semantic-aware Single-image Sticker Personalization with a Large-scale Sticker-tag Dataset},
author={Changhyun Roh and Yonghyun Jeong and Jonghyun Lee and Chanho Eom and Jihyong Oh},
year={2026},
eprint={2604.26883},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2604.26883},
}